

Retrieval Sources (RAG)
What it does
Section titled “What it does”Retrieval Sources (RAG) registers the systems Arbitex can retrieve grounding content from — a vector database, web crawler, S3 bucket, Confluence space, or SharePoint site — through a typed connection form rather than raw JSON.
Configure in the UI
Section titled “Configure in the UI”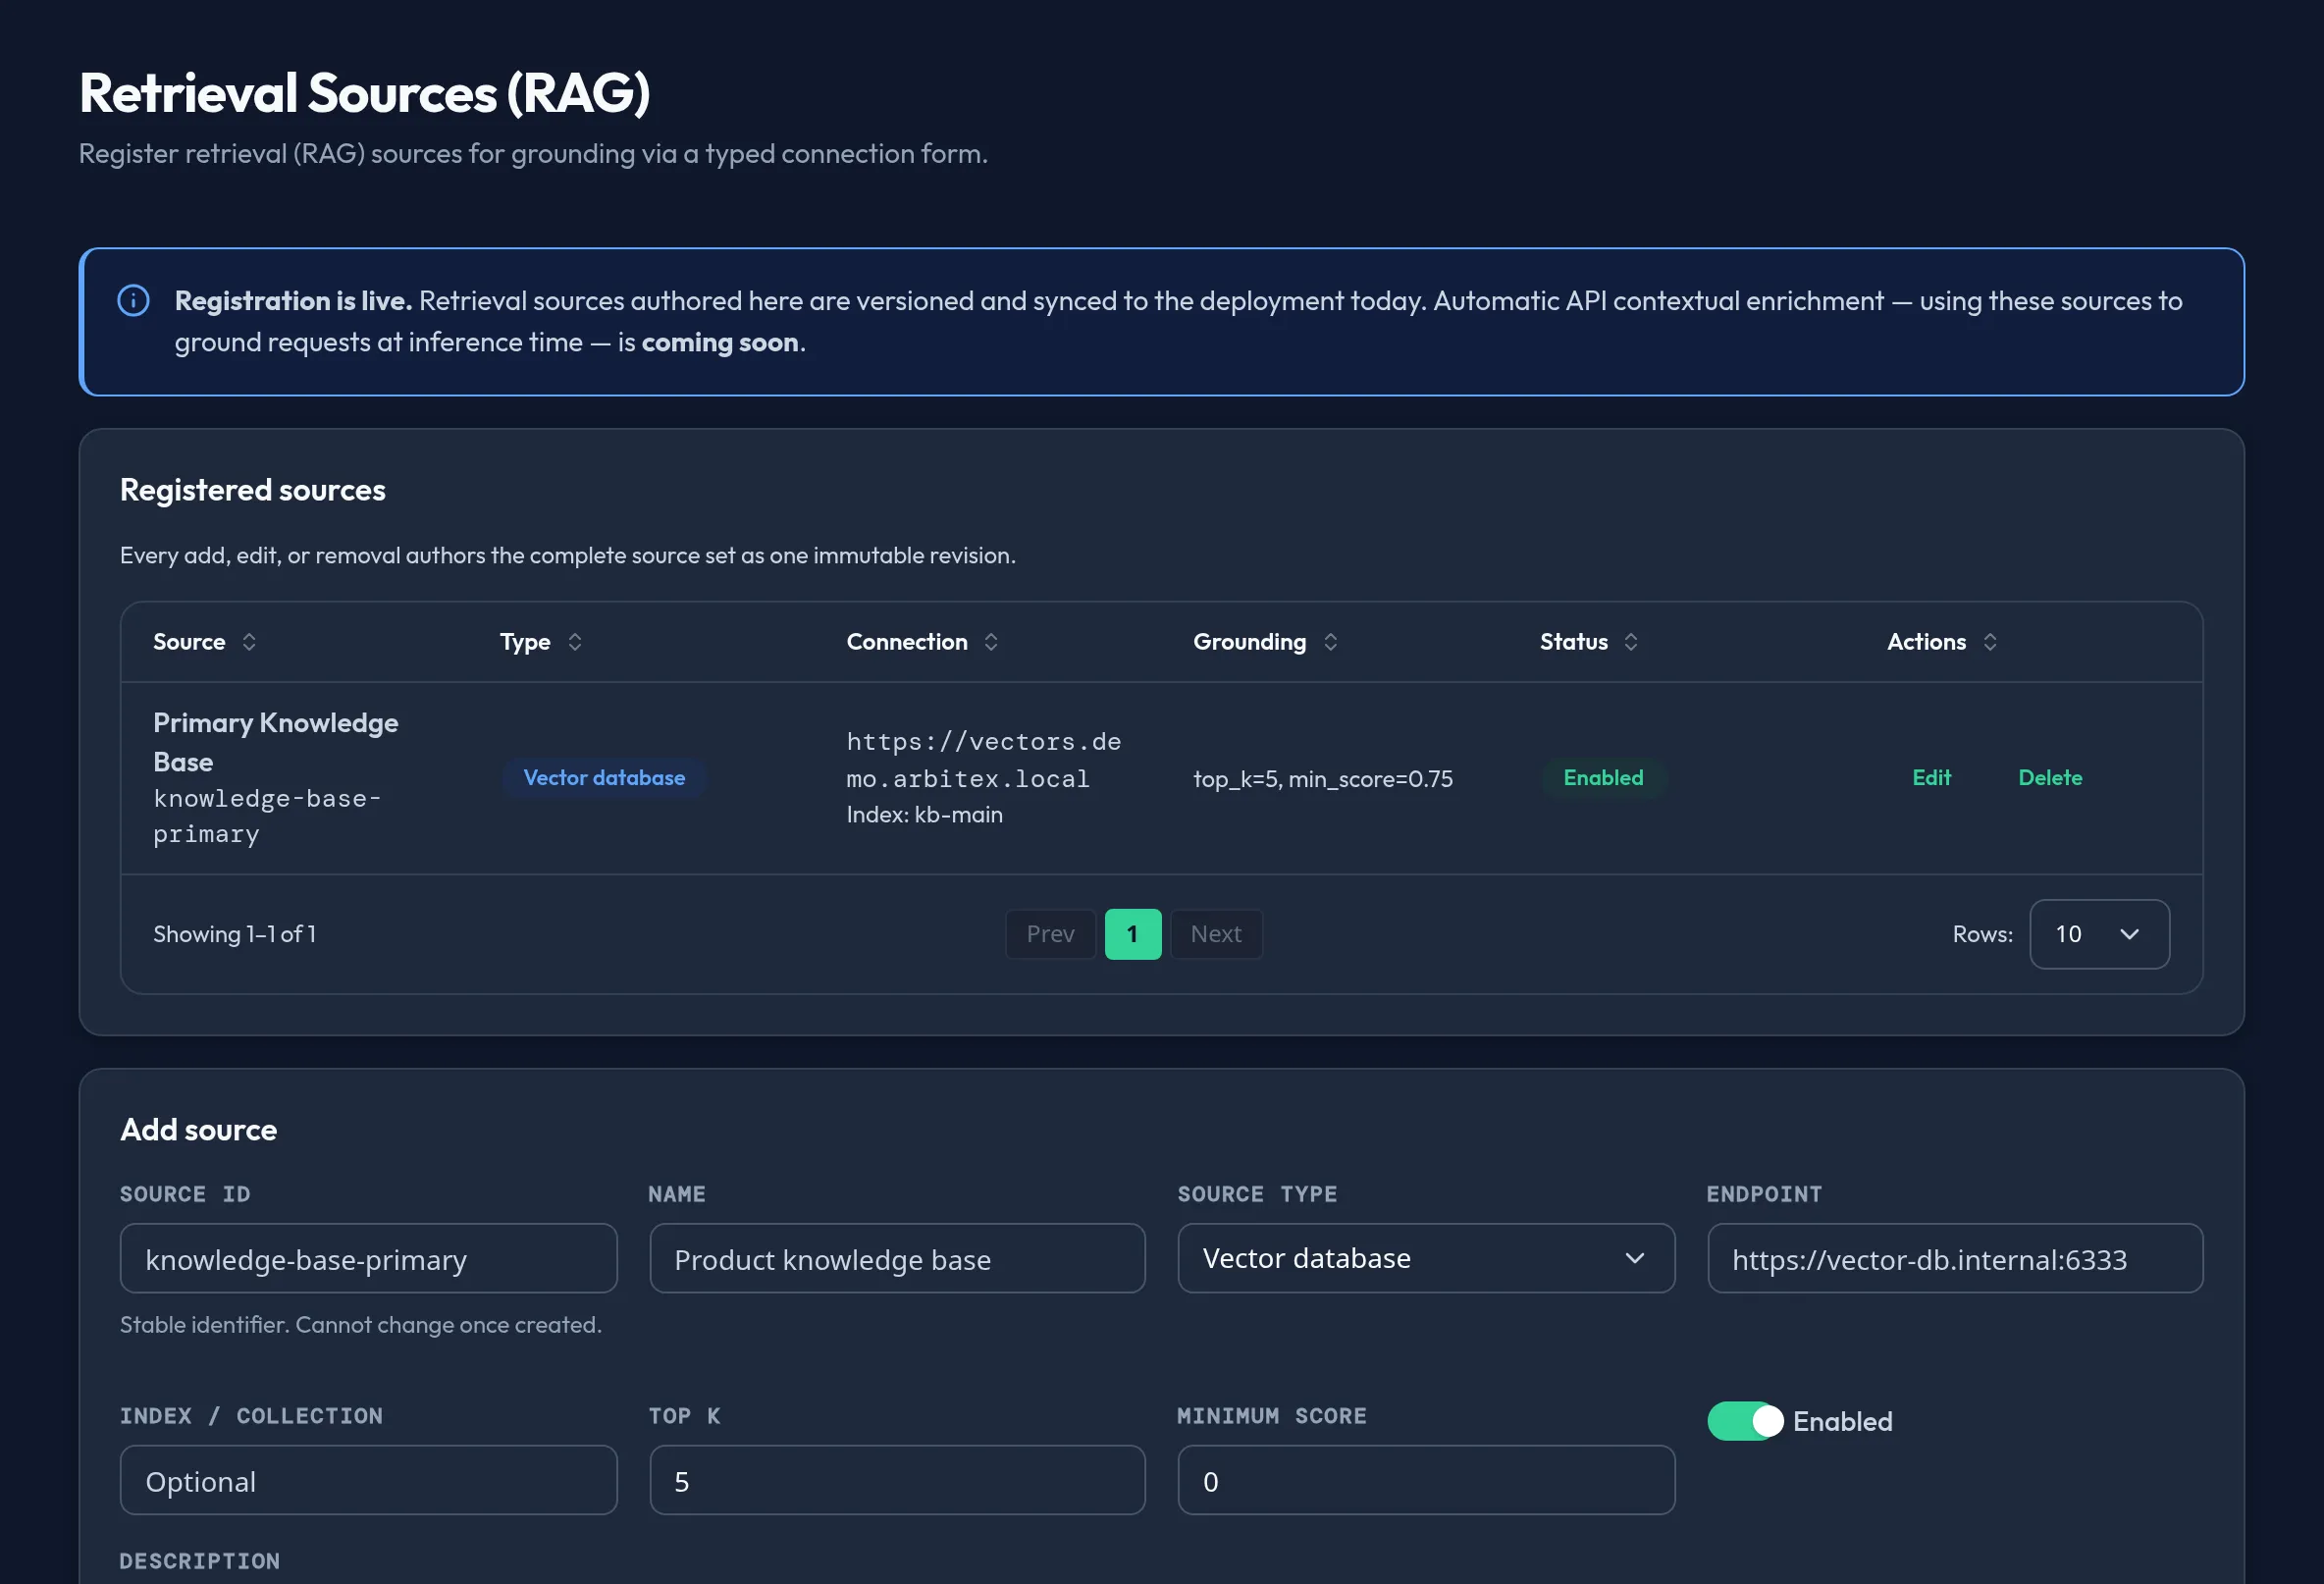
-
Open Models & Routing → Retrieval Sources (RAG).
-
Set a Source ID — a stable identifier you cannot change once created — a Name, and a Source type: Vector database, Web crawler, S3 bucket, Confluence, or SharePoint.
-
Enter the Endpoint the source is reachable at, and optionally an Index / collection name.
-
Tune retrieval with Top K (how many results to retrieve) and Minimum score (the relevance threshold), then toggle Enabled and save.
-
The table lists every source’s Type, Connection (endpoint and index), Grounding settings (
top_k/min_score), and Status — with Edit and Delete row actions.
API equivalent
Section titled “API equivalent”curl -X POST "https://admin.arbitex.ai/api/v1/admin/models-routing/retrieval-sources/list" \ -H "Authorization: Bearer $ADMIN_TOKEN" \ -H "Content-Type: application/json" \ -d '{"du_id": null}'curl -X POST "https://admin.arbitex.ai/api/v1/admin/models-routing/retrieval-sources/set" \ -H "Authorization: Bearer $ADMIN_TOKEN" \ -H "Content-Type: application/json" \ -d '{"du_id": null, "objects": [{"object_key": "knowledge-base-primary", "name": "Product knowledge base", "source_type": "vector_db", "endpoint": "https://vector-db.internal:6333", "top_k": 5, "min_score": 0.75, "enabled": true}]}'set is replace-all for the segment — every add, edit, or delete re-authors
the complete source set as one revision. There is no test-connection action
on this page today.
Plan & availability
Section titled “Plan & availability”Retrieval Sources (RAG) is available on every plan.
Deployment notes
Section titled “Deployment notes”The Endpoint must be reachable from wherever the request is served. On a Hybrid Outpost, a vector database or S3-compatible endpoint inside your network works well; Web crawler, Confluence, or SharePoint sources that need internet reachability will not function from an air-gapped outpost without an internal mirror.
Related
Section titled “Related”- Model Catalog — models that will eventually consume grounded context from these sources.
- MCP Servers — another typed connection surface, for tool servers rather than retrieval sources.